Treating Prompt Templates as Tunable Hyperparameters in Scikit-Learn GridSearchCV

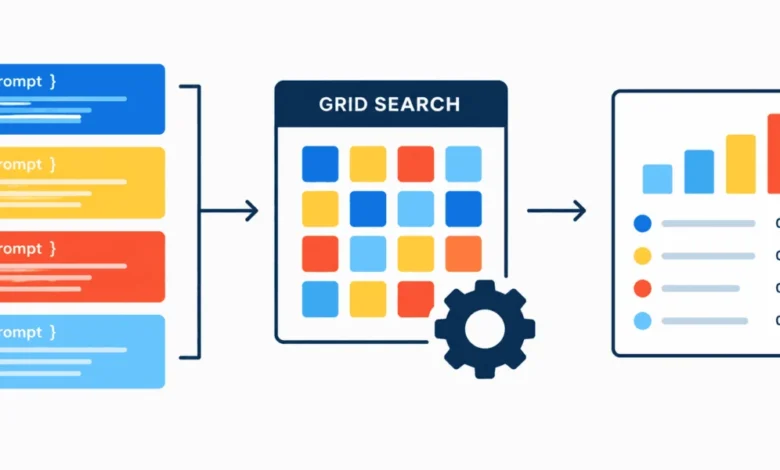
The rapid evolution of Large Language Models (LLMs) has fundamentally shifted the paradigm of machine learning development. Where engineers once focused exclusively on architectural adjustments or weight fine-tuning, a significant portion of contemporary AI optimization now resides in the domain of prompt engineering. By treating prompt templates as tunable hyperparameters within the robust framework of scikit-learn’s GridSearchCV, data scientists can move beyond manual, intuition-based prompt design toward a data-driven, systematic optimization process. This methodology allows for the automated discovery of optimal instruction sets, effectively turning the qualitative art of prompting into a quantitative engineering discipline.
The Shift Toward Systematic Prompt Engineering
In traditional machine learning workflows, hyperparameter optimization—the process of searching through a defined space of configuration settings—is a cornerstone of model deployment. Techniques such as grid search and random search have historically been used to calibrate learning rates, tree depths, or regularization strengths to maximize predictive performance. As LLMs become integrated into standard classification pipelines, the prompt itself has emerged as the most critical "hyperparameter."
Unlike weight-based training, which modifies the internal state of a neural network, prompt optimization modifies the external instruction set provided to the model. Because the same model can produce vastly different outputs based on slight variations in phrasing, context, or persona, the ability to test these variations programmatically is a significant advancement. By wrapping an LLM within a custom class compatible with scikit-learn’s API, developers can subject various prompt candidates to cross-validation, ensuring that the selected prompt is not merely effective on a single data point, but robust across a diverse subset of the training data.
Chronology of Automated Prompt Optimization
The integration of LLMs into standard machine learning libraries like scikit-learn represents a major milestone in the democratization of AI. For years, the "prompt engineering" community relied on trial and error—a process often described as "alchemy" rather than "engineering."
- The Manual Era (2020–2022): Early adopters of GPT-3 and similar models spent hours manually refining prompts, relying on anecdotal evidence to determine which phrasing elicited the best responses.
- The Evaluator Era (2023): The introduction of LLM-as-a-judge frameworks allowed for automated evaluation, but these systems often lacked the rigor of traditional statistical validation.
- The Integration Era (2024–Present): The current shift involves treating LLMs as standard scikit-learn estimators. By leveraging classes like
BaseEstimatorandClassifierMixin, developers can now integrate LLMs directly into existing Scikit-Learn pipelines, enabling the use ofGridSearchCVto iterate over prompts with the same ease as tuning a random forest’s hyperparameters.
Implementation: Building a Scikit-LLM Bridge
To implement this, one must first initialize a model pipeline. Utilizing efficient, smaller-scale models such as Qwen/Qwen2.5-0.5B-Instruct provides an excellent balance between performance and computational cost. The architecture requires a custom wrapper class that implements the fit and predict methods. The fit method serves as a placeholder to maintain compatibility with scikit-learn’s API, while the predict method handles the heavy lifting: formatting the input text according to the current template, querying the LLM, and parsing the output for classification labels.
import numpy as np
from sklearn.base import BaseEstimator, ClassifierMixin
from sklearn.model_selection import GridSearchCV
from transformers import pipeline

# Initializing the model pipeline
generator = pipeline("text-generation", model="Qwen/Qwen2.5-0.5B-Instruct")

class ZeroShotPromptClassifier(BaseEstimator, ClassifierMixin):
    def __init__(self, generator, prompt_template="Classify as positive or negative: text"):
        self.generator = generator
        self.prompt_template = prompt_template

    def fit(self, X, y=None):
        return self

    def predict(self, X):
        predictions = []
        for text in X:
            prompt = self.prompt_template.format(text=text)
            messages = ["role": "user", "content": prompt]
            output = self.generator(messages, max_new_tokens=5, pad_token_id=self.generator.tokenizer.eos_token_id)
            reply = output[0]['generated_text'][-1]['content'].strip().lower()
            if "positive" in reply:
                predictions.append("positive")
            elif "negative" in reply:
                predictions.append("negative")
            else:
                predictions.append("unknown")
        return np.array(predictions)
This structural approach allows for the creation of a param_grid, where the user defines multiple variations of a prompt. The GridSearchCV object then manages the cross-validation process, systematically testing each prompt against the dataset and scoring performance based on user-defined metrics such as accuracy or F1-score.
Supporting Data and Statistical Justification
The efficiency of this approach is backed by the principles of statistical learning theory. When a developer tests three or four variations of a prompt, they are essentially exploring a discrete search space. While the number of potential prompts is theoretically infinite, the subset of effective prompts is often narrow. By using 2-fold or 5-fold cross-validation, the developer ensures that the prompt is not overfitting to a specific batch of examples.
For instance, in a four-sample test set (as demonstrated in basic experiments), the grid search may yield a 75% accuracy rate for a prompt like "Analyze this review. Output ‘positive’ or ‘negative’: text." This data-driven result provides a concrete justification for choosing one phrasing over another, replacing subjective preference with empirical evidence. As the dataset grows, this method becomes even more powerful, providing a clear statistical trajectory of how prompt complexity influences model performance.
Broader Implications and Industry Impact
The shift toward treating prompt templates as hyperparameters has profound implications for the industry. First, it standardizes the development lifecycle. Organizations that already use MLOps platforms to track experiments can now integrate prompt versions into their experiment tracking logs, treating a prompt change with the same level of scrutiny as a change in the training dataset.
Second, it enhances reproducibility. In a research or production environment, knowing exactly which prompt configuration yielded the best results is critical for auditing and compliance. By version-controlling prompt templates alongside model configurations, teams can ensure that their AI systems remain predictable and transparent.
Finally, this methodology bridges the gap between traditional software engineering and generative AI. It allows developers to apply familiar tools—such as scikit-learn—to modern AI problems, reducing the learning curve for those transitioning from classical machine learning to LLM-based systems. As models become more nuanced, the ability to fine-tune instructions programmatically will likely become a standard requirement for high-performance AI deployment.
Best Practices for Large-Scale Deployment
While the example provided focuses on a small dataset for clarity, scaling this approach requires careful consideration. When deploying this in a production environment:
- Prompt Sanitization: Ensure that prompt templates are properly escaped and sanitized to prevent injection attacks or unintended formatting errors.
- Computational Budget: Grid searching across large numbers of prompts can be computationally expensive. Use randomized search (
RandomizedSearchCV) if the number of prompt variations is large, as it samples from the search space rather than exhaustively testing every combination. - Caching Results: Since LLM inference is time-consuming, cache the outputs of specific prompt-input pairs. If a specific prompt has already been tested against a piece of text, there is no need to re-query the model.
- Validation Diversity: Ensure that the evaluation set used during the grid search is representative of the production data. A prompt that works well on short reviews may fail on long-form documentation.
In conclusion, the integration of prompt templates into standard machine learning optimization workflows is a critical step forward. By leveraging existing infrastructure to automate the discovery of optimal instructions, developers can ensure that their models are not only performing at their peak but are also grounded in a repeatable, verifiable, and data-driven process. This transition from "prompting by intuition" to "prompting by grid search" represents the professionalization of generative AI development.