Google has officially launched Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, marking a major leap forward in the development of real-time voice dialogue models. Authored by Principal Engineer Tom Ouyang and Member of Technical Staff Malini Jaganathan on behalf of the Gemini Audio Team, the announcement highlights significant improvements in parallel reasoning and artificial intelligence capabilities. These updates are engineered to make human-AI collaboration more intuitive, allowing users to execute complex tasks smoothly using natural voice commands across various Google platforms, including the Gemini mobile application, Google Workspace, and Google Search.
Evolution of Real-Time Voice Agents
The introduction of Gemini 3.8 Live and its extended thinking counterpart represents the culmination of years of iterative development in speech-to-speech architecture. Historically, voice assistants relied on cascading systems—converting speech to text, processing the text through a language model, and then synthesizing the text back into speech. This traditional pipeline often introduced noticeable latency and stripped away vital emotional or contextual nuances present in human vocal delivery.
Recent advancements in native multimodal architectures have fundamentally shifted this landscape. By processing audio natively, models can perceive tone, pacing, and intent with far greater accuracy. The Gemini 3.8 generation builds upon this foundation by integrating advanced parallel reasoning mechanisms. This allows the model to think through complex problems or execute multi-step tool calls asynchronously while maintaining an unbroken, natural conversational flow with the user.
Performance Benchmarks and Empirical Data
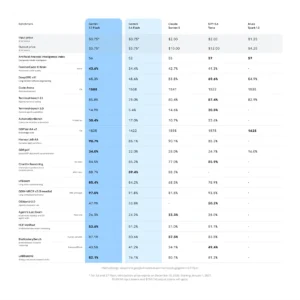
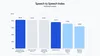
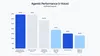
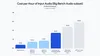
Independent evaluations and internal metrics demonstrate that the new models perform at the frontier of conversational AI. According to data from Artificial Analysis, Gemini 3.8 Live Extended Thinking captured the number one overall position on the Speech-to-Speech Quality Index, scoring an impressive 82.6. In specialized agentic task completion evaluations, the model achieved 68.6% on the $mathcalI$-Voice benchmark and 35.1% on Sierra’s $mathcalI$-Voice-banking benchmark. Furthermore, it demonstrated strong foundational reasoning capabilities by scoring 97.7% on Big Bench Audio while maintaining a cost structure competitive with other industry-leading frontier models.

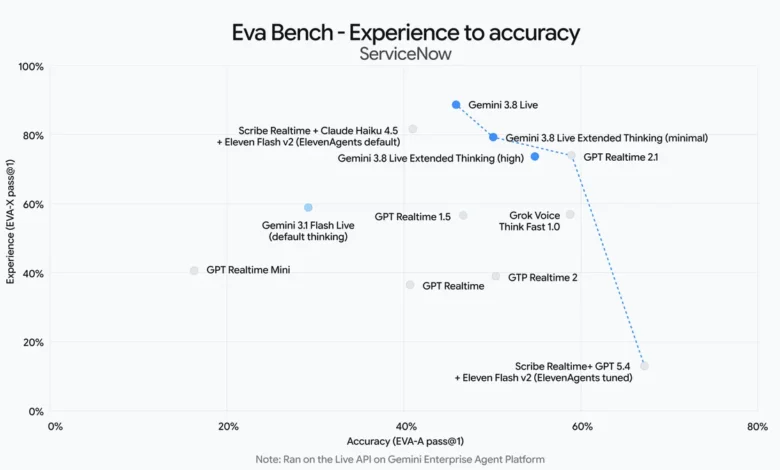
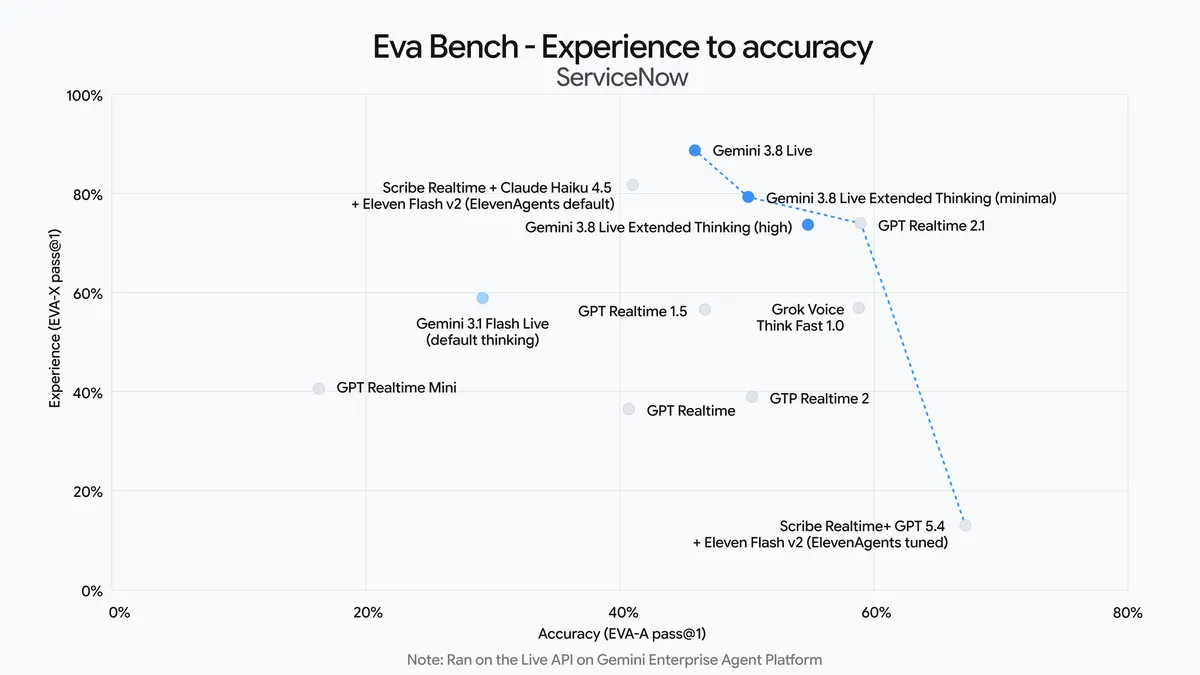
Gemini 3.8 Live also secured a strong second-place standing in the Speech Agent Arena. Beyond pure score metrics, the model excels on ServiceNow’s EVA-Bench—a rigorous evaluation framework designed to test voice agents on complex enterprise workflows. On EVA-Bench, the Gemini Live models successfully pushed the Pareto Frontier, demonstrating an optimal balance between high task accuracy and natural conversational quality.
Core Capabilities and Technical Enhancements
The new suite of models introduces several technical features designed to streamline both consumer experiences and enterprise deployments:
- Near Real-Time Visual Integration: Gemini 3.8 Live can process visual inputs seamlessly alongside audio streams. Whether analyzing a live video feed to troubleshoot hardware, guiding an employee through an onboarding process in real time, or playing a game of chess by observing the board state, the model utilizes visual context to enrich its spoken responses.
- Multilingual Fluency: The models feature automated language detection capable of fluidly identifying and transitioning between 97 supported languages mid-conversation without requiring manual setting adjustments.
- Asynchronous Tool Execution: The system can execute background API calls and tool integrations while maintaining dialogue. If a task requires extended processing, the model utilizes early verbal cues—such as acknowledging a prompt with phrases like "Let me check that"—and provides live progress narration to keep the user informed.
- Extended Thinking and Verbal Progress Tracking: For heavy reasoning tasks, Gemini 3.8 Live Extended Thinking reasons and speaks simultaneously, breaking down complicated workflows, synthesizing raw code from sketches, or generating comprehensive marketing plans on the fly.
Integration Across Consumer and Enterprise Ecosystems
For everyday users, the capabilities of Gemini 3.8 Live are rolling out directly into popular Google products. Within Google Workspace, tools such as Docs Live, Gmail Live, and Keep Live allow users to draft documents, manage correspondence, and organize notes through hands-free collaboration. In Google Search Live, users can receive step-by-step, real-time troubleshooting guidance for technical issues, home repairs, or educational inquiries.
For developers and enterprise organizations, the models are accessible via the Gemini Live API. Google has established strategic integrations with major developer platforms—including Agora, Fishjam, LangChain, LiveKit, Pipecat, Vercel, and Vision Agents. These platforms manage the underlying real-time media streaming infrastructure, enabling developers to build high-performance voice interfaces without needing to architect complex streaming pipelines from scratch.
Industry Reception and Partner Testimonials
Enterprise leaders across diverse sectors have embraced the new models, pointing to their low latency, contextual depth, and robust tool-calling functionality as key drivers for adoption. Representatives from enterprise software giants and specialized AI platforms—such as Salesforce, Genspark, Lumeris, Lenskart, and ServiceNow—have noted that the models bridge the gap between traditional customer service automation and human-level conversational empathy.
Business analysts suggest that the ability of voice agents to handle asynchronous background tasks while sustaining a natural dialogue will significantly accelerate enterprise automation, particularly in sectors like healthcare, retail, and financial services where multi-step verification and database lookups are routine.
Safety, Transparency, and Responsible AI
As generative audio technology becomes more sophisticated, issues regarding authenticity, misinformation, and deepfakes remain paramount. To address these challenges, Google has integrated its SynthID watermarking technology into all audio outputs generated by the new Gemini models.
SynthID embeds an imperceptible, digital watermark directly into the audio waveform. This watermark remains detectable even after compression, recording, or analog-to-digital conversions, allowing platforms and users to identify AI-generated speech reliably. Google notes that this deployment aligns with its broader framework for responsible AI development, with comprehensive safety evaluations detailed in the official model card for Gemini 3.8 audio.
Rollout Timeline and Availability
The rollout of Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking begins immediately. Enterprise clients can access the models through the Gemini Enterprise Agent Platform and the Gemini Live API, while consumer-facing features will deploy progressively across the Gemini mobile application, Google Workspace integrations, and Search Live over the coming weeks.